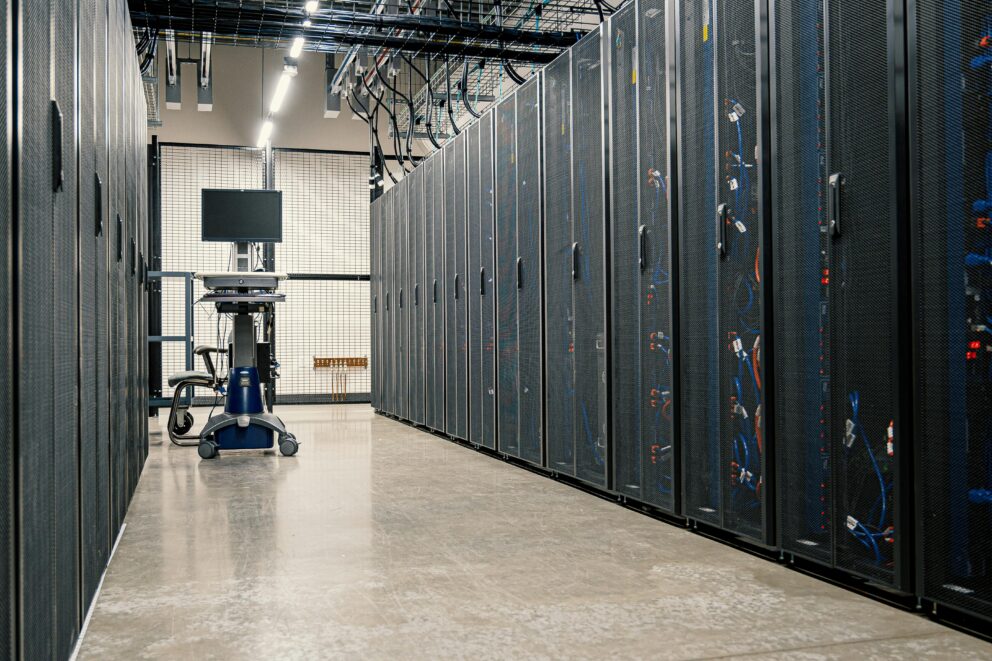
AI datacentre hardware is in very short supply. GPU servers and high-speed switching are both suffering from long lead times when buying new from the OEM, and every new generation of hardware means that you now have previous-generation kit to decommission and recover, which other buyers may be actively looking for.
However – that previous-generation kit is not just something that should be scrapped or recycled. If you handle it properly, you can recover value from it to help fund part of the next upgrade – as well as supporting the circular economy by keeping working hardware in service for longer.
But how exactly do you decommission and recover value from AI datacentre hardware? And where can tested refurbished and hyperscaler-surplus kit fill the gaps left by extensive lead times in OEM-new supply?
Hardware supply constraints: there is simply not enough supply to meet demand
Demand for AI capacity isn’t where the problem lies. Training clusters, inference platforms and enterprise AI projects all need hardware, and the hardware supply chains behind them have not kept pace. This lack of supply is inevitably driving up prices – Gartner forecasts that DRAM prices will increase by 125% over 2026 with no meaningful pricing relief expected until late 2027 at the earliest.
As a datacentre operator you will be well aware that, for example, the newest NVIDIA GPUs and the systems built around them can’t just be ordered off the shelf – they are actually allocated, such is the demand for them. Hyperscalers and the largest cloud providers have the first pick of new stock, so smaller operators, colocation providers and enterprise buyers just have to wait it out.
The same pressure exists through the rest of the infrastructure: shipping delays on high-speed switches, optics, memory and even power can all hold up a deployment. When one component is late or on back order, the whole cluster has to wait. A rack of GPU servers can’t do anything if you’re still awaiting delivery of the low-latency switch fabric and optics that connect it. Each new generation of accelerators raises the price of entry. Buying at the top of the range for every single workload is hard to justify, especially for inference and development clusters that don’t necessarily need the latest chips to do their job.
That is why more operators now mix sources: they buy new where it’s unavoidable (and they can tolerate the long lead times) and use tested refurbished and surplus hardware to fill the rest of the build – meaning they can build faster and at lower cost.
This is where DTC comes in – we can provide you with kit right now, without you having to wait for an allocation from the OEM.
Three ways operators can source AI datacentre hardware
There are three routes to market for AI datacentre hardware. Most operators end up using more than one out of necessity – either due to cost, or because mixing sources is the only way to get a deployment out on time.
OEM new
Buying direct from the manufacturer or an authorised partner gets you the latest generation, full vendor support and a clean warranty. It also brings the longest lead times and the highest cost. New is the right choice for frontier training clusters, because the newest GPUs will make a measurable difference over older hardware.
Hyperscaler surplus
Hyperscalers refresh on their own schedule, and when they do, large volumes of capable, standardised hardware are recovered from their datacentres. Much of it is only one generation behind the frontier release and has plenty of working life left. DTC sources hyperscaler surplus equipment directly, tests it, and supplies it to operators who need volume without having to wait for allocation.
Refurbished secondary market
Refurbished hardware is what DTC does best and where we can help you the most. Equipment is recovered, tested, repaired where needed and sold with a warranty. It suits inference clusters, development and test environments, network expansion and spares, where proven hardware does the job at a lower price. We supply GPU servers across all generations, including Dell PowerEdge, HPE ProLiant, Lenovo ThinkSystem and NVIDIA DGX systems, and if we do not have it in stock, we can source it from the broker market.
Comparing the different ways you can source AI hardware
| OEM new | Hyperscaler surplus | Refurbished | |
|---|---|---|---|
| Cost | Highest | Lower | Lowest |
| Lead time | Longest, usually allocated | Short when stock is available | Short, often from stock |
| Generation | Current | Usually one generation back | Current to several generations back |
| Warranty | OEM warranty | Supplier warranty | Supplier warranty |
| Support | OEM support contract | Third-party maintenance | Third-party maintenance |
| Best fit | Frontier training | Volume builds, inference | Inference, test, expansion, spares |
Whichever route you choose, check how each unit was tested, what the warranty covers, and that you get a data erasure record from the previous owner.
Need hardware sooner than your OEM can deliver? Ask us about refurbished supply and network spares.
Decommissioning AI datacentre hardware in five steps
Every time you put new kit into an AI datacentre, you need to plan for when that kit will need to be replaced – because it will eventually need to be decommissioned and recovered. The servers, switches, optics and power equipment coming out of the hall need to be removed safely, wiped to a standard you can prove, and either resold or recycled. Done well, decommissioning returns money to the business. Done poorly, it creates data risk, compliance exposure and hardware that’s now been recycled that someone else might have paid for.
1. Plan the kit’s exit as soon as it goes in
Accelerator generations now turn over faster than traditional enterprise servers ever did. As Blackwell-class systems arrive, Hopper-generation servers come out, and the network, storage and memory around them often have to come out at the same time. The result is more hardware leaving the datacentre, more often. This kit coming out is not scrap – it very often has good resale value.
The quicker your older kit is recovered and remarketed, the more it’s worth.
2. Remove it from production or offline halls
DTC decommissions equipment in live and offline environments. In a live hall, that means removing retired equipment while production systems keep running. In an offline hall, it means clearing the space completely.
Every asset is recorded as it comes out, so you have a full audit trail from rack position to final outcome. Equipment is packed on site and moved into secure storage for the next stage. Find out more about our equipment recovery service.
3. Wipe it: certificated data destruction
AI hardware holds sensitive data in more places than most people expect: NVMe drives in GPU servers, storage arrays holding training datasets and model checkpoints, and configuration data on switches and management controllers.
We have a Data Cleansing Lab which uses industry-recognised automated erasure software. Every data-bearing asset is wiped and issued with a certificate of destruction. You get documentary proof for every item, ready for your auditors and your customers.
4. Recover the value: buyback for every GPU generation
DTC buys back AI datacentre hardware across every GPU generation. If it has a second life, we will find it a home, and we can return value to you.
Each item is audited, tested and valued. Equipment with secondary-market value is remarketed through our global broker network. That includes GPU servers from Dell PowerEdge, HPE ProLiant, Lenovo ThinkSystem and NVIDIA DGX ranges, switching from Cisco, Juniper and Arista, optical transceivers and power equipment.
5. Recycle what cannot be resold: WEEE-compliant, zero to landfill
Hardware that cannot be resold is recycled responsibly. DTC operates WEEE-certified, zero-to-landfill recycling, with equipment hand-disassembled and separated into material streams for compliant processing. DTC holds an Environment Agency ATF licence and BSI ISO 14001 accreditation. See how we handle network equipment recycling.
Retiring AI hardware? Talk to DTC about decommissioning and buyback.
Keeping AI clusters running in the meantime
Once a cluster is live, downtime is expensive. Idle GPUs still cost money, and a single failed switch or optic can take a training run or inference service offline.
DTC holds spares for the equipment in your estate, so a failed part can be swapped quickly rather than waiting on an OEM replacement. Our engineers provide on-site remote hands for swaps, patching and migrations through our technical network services. And when your OEM support contract ends, third-party maintenance keeps previous-generation switching, servers and optics supported, so you can keep running proven hardware instead of replacing it on the vendor’s schedule.
Talk to us about AI datacentre hardware
Whether you are retiring a hall of previous-generation GPU servers, need hardware faster than your OEM can deliver, or want spares and support for an existing cluster, DTC can help. Tell us what you have or what you need, and our team will come back to you with options.